Assurance architecture
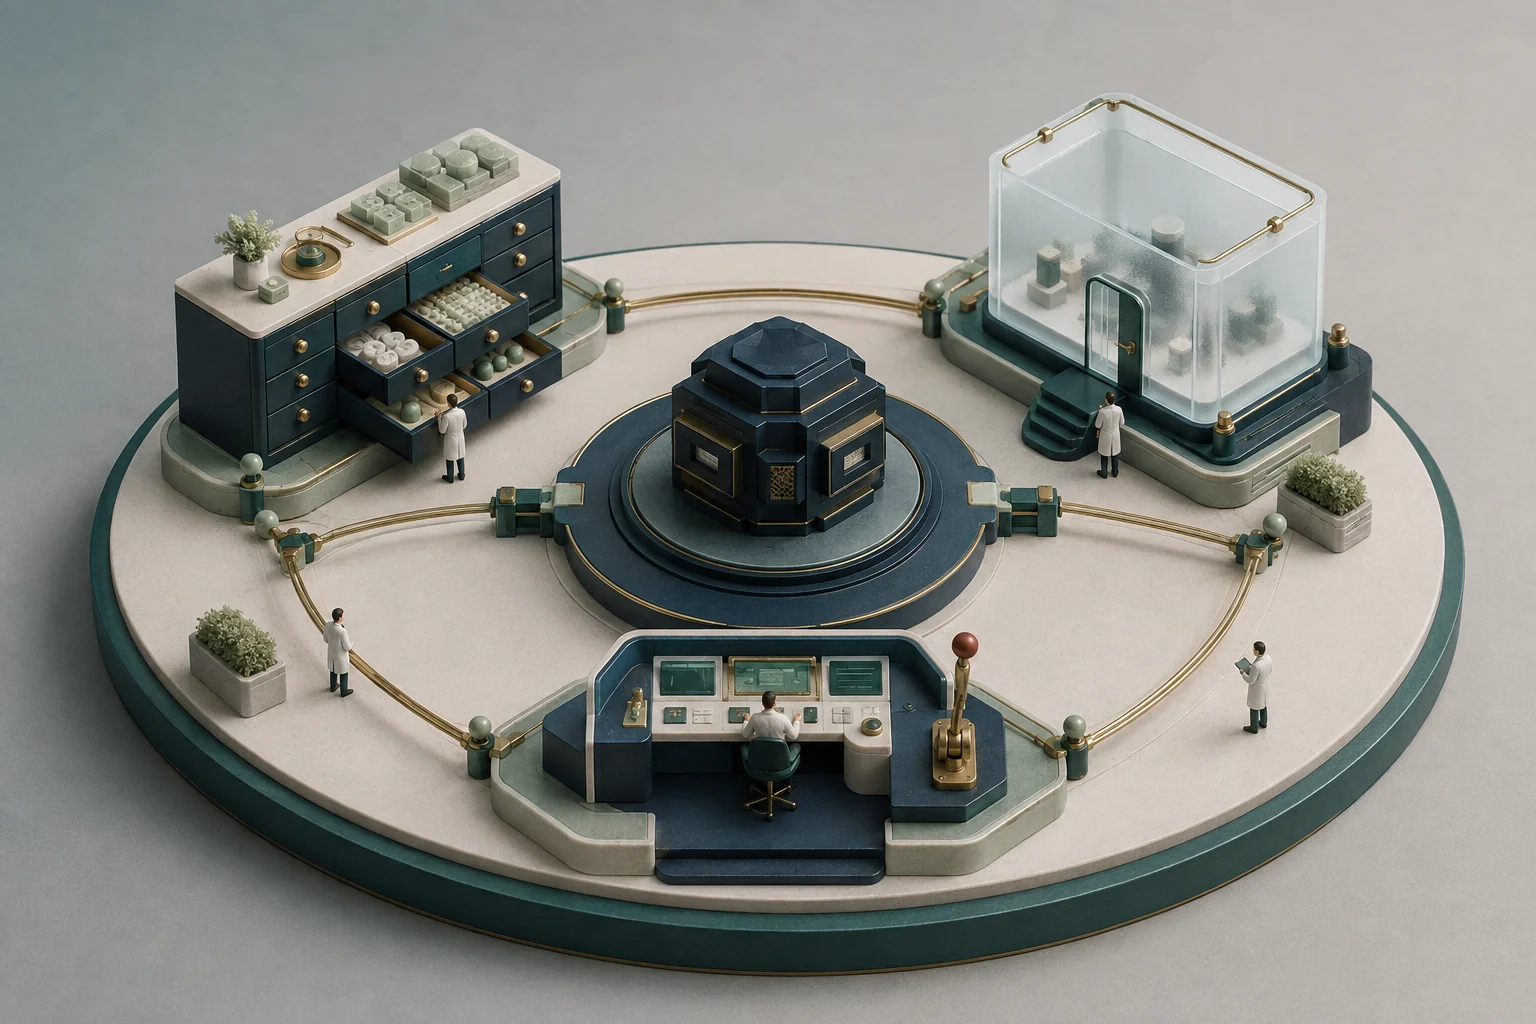
The proposed architecture separates generation, permission to act and verification. This supports both AI-assisted QE workflows and the testing of AI applications.
Explore the architecture in 3D → · Orbit the model and compare generated-test verification, AI evaluation, denied actions and failed quality checks. A 49-second film and editable Blender scene are also available. These are authored illustrations of this logical architecture, not a live system or a performance simulation.
Adoption foundations
The runtime architecture assumes a usable delivery system. Before connecting client tools, validate the infrastructure, platform and workflow dependencies: repeatable environments and pipelines, isolated data, controlled external dependencies, testable interfaces, owned frameworks and evidence, approved AI access, reviewer capacity and platform operation. A missing foundation changes the pilot boundary, cost and timing. Cloud migration, Kubernetes and retrieval infrastructure are design choices, not universal prerequisites.
A control boundary around agent actions
Overview · all connections have equal emphasis.
Moving pulses show direction. Play flow follows specific paths through the architecture.
Pan horizontally to explore the full diagram. A text description is available below.
Inspect a component: Select a component in the diagram
Context service. Scope retrieval to permitted sources and preserve the input version. Repository text remains task data, even when it contains instructions. [A03][R01]
QE agent runtime. Record the model and prompt version; bound retries, memory and spend. The runtime proposes work within the gateway’s authority. [A01][R01]
Action gateway. Enforce identity, resource scope and approvals outside the model. An injected instruction cannot grant the agent a production permission. [A03][R01]
Independent checks. Run generated tests in a sandbox. Validate repeatability and fault detection against an approved oracle before accepting a candidate. [E04][E05]
Evaluation service. Compare application versions on held-out cases and denied-action scenarios. Calibrate model judges against reviewed human labels. [A01][T03][T06]
Evidence store. Join the task, run, review and outcome. Measure verification and correction effort alongside generation time and quality. [D02][E01]
Research behind this design & diagram description
NIST frames assurance across the lifecycle. OWASP and OSFI identify agent identity, tool authority and traceability as control concerns; Meta separates generation from validation.
Design implicationSeparate context, generation, policy enforcement, independent evaluation and release authority. Preserve a shared evidence record across those boundaries.
Engineers and delivery systems supply tasks and approved context. The runtime proposes actions through a policy gateway. Independent sandbox checks and application evaluations supply evidence to the release authority. Traces and decisions feed the evidence store; curated failures become regression cases.
Inspect methods and source documents →An agent may suggest a tool call, but a separate enforcement point decides whether that identity can perform the action on the specified resource. Prompt instructions are not an access-control mechanism. Retrieved documents, repository text and tool results should be treated as untrusted content.
For the initial QE pilot, use scoped non-production context, a sandbox and draft artifacts. More consequential actions require a separate design review of authority, approvals, recovery and evidence. The detailed pilot control mapping remains applicable.
A workflow through the architecture
Overview · all connections have equal emphasis.
Moving pulses show direction. Play flow follows specific paths through the architecture.
Pan horizontally to explore the full diagram. A text description is available below.
Research behind this design & diagram description
Meta’s generation work filters candidates through executable checks; mutation-guided testing tests whether a candidate detects a fault. Agent guidance requires authority to be bounded at the action boundary.
Design implicationGenerate a negative-amount test from an approved contract, execute it through a scoped gateway, retain the independent fault-detection result and route the evidence to a human reviewer.
The engineer supplies the contract. The agent requests scoped context and proposes a test. The gateway authorizes sandbox execution. CI checks the candidate against a seeded boundary fault. The reviewer receives assertions and test evidence before using existing merge controls.
Inspect methods and source documents →Evaluation extends across the lifecycle
Pan horizontally to explore the full diagram. A text description is available below.
Research behind this design & diagram description
NIST treats evaluation and risk management as lifecycle activities. Evaluation product documentation supports versioned datasets and comparisons; judge calibration still requires local evidence.
Design implicationCompare baseline and candidate configurations against held-out cases, gate releases on agreed floors, then turn reviewed production failures into regression cases.
Versioned application configurations and a held-out evaluation corpus feed comparable runs and independent scoring. A failed release gate holds the change for investigation. A passing gate leads to controlled deployment and production monitoring; curated failures refresh the corpus.
Inspect methods and source documents →A useful evaluation contract identifies the user task, representative populations, important failure modes, expected behavior, scoring rules and release thresholds. Split development examples from a held-out evaluation set, and preserve a history of model, prompt, retrieval, dataset and tool versions.
| What is evaluated | Example evidence | Important limitation |
|---|---|---|
| Task outcome | Correct result against an independent expected outcome | Fluency is not correctness |
| Retrieval and grounding | Relevant evidence; correct attribution; permission-aware retrieval | A citation can point to an irrelevant or inaccessible source |
| Agent trajectory | Correct tool, arguments, scope and termination | A successful final answer can hide an unsafe action |
| Adversarial resilience | Injection, data disclosure and denied-action scenarios | A finite suite does not prove absence of other failure modes |
| Operational behavior | Latency, cost, escalation, drift and fallback success | Average performance can hide rare severe failures |
LLM judges can help scale assessment, but they need calibration against expert labels and checks for inconsistency and bias. Deterministic contracts and human review still have distinct roles. [A01][A02][T03][T06]
The release decision includes the AI configuration
Re-run relevant evaluations when changing prompts, models, retrieval indexes, tool schemas, permissions or memory behavior. Maintain bounded retries, budget limits and a tested fallback. Curate incidents into regression cases without copying sensitive production content into broadly accessible datasets.
OWASP’s 2026 LLM guidance covers the model as an application component; its agentic guidance extends the threat model to actors with tools and memory. The newly introduced ACS proposes common runtime control hooks. Its implementation maturity should be evaluated before relying on framework portability. [A03][A04][A05]
Verify the authority boundary
Pan horizontally to explore the full diagram. A text description is available below.
Research behind this design & diagram description
OWASP identifies risks arising from untrusted inputs and agent tool use. OSFI’s July 2026 bulletin discusses agent identity, scoped tool access, traceability and resilience as sound practices.
Design implicationTest the system’s response when poisoned context asks for an unauthorized action. Assert no side effect, a recorded denial and a bounded escalation path—not just a polite refusal in the model’s answer.
Untrusted documents, code, tool output and memory reach the agent runtime. The agent can request an action, but the gateway checks identity, resource and policy. Permitted calls reach scoped tools. Denied calls cause no side effect and stop or escalate.
Inspect methods and source documents →Detailed architecture walkthroughs
The expanded technical briefing develops the logical platform into concrete boundaries and failure paths. These are authored designs informed by the source library, not claims that a publisher or institution uses this exact architecture.
| Architecture concern | Visual walkthrough |
|---|---|
| Context and reproducibility | Permission-aware retrieval and versioned release manifest |
| Generated-test validity | Independent expected behavior and mutation-guided tests |
| Test operations | Evidence-linked failure diagnosis and flaky-test repair |
| Evaluation assets | Corpus lifecycle and judge calibration |
| Agent authority | Denied-action sequence and execution zones |
| Release and resilience | Release decision logic and fallback state machine |
| Operational evidence | Telemetry pipeline and integration contracts |
Financial-services context
OSFI’s July 2026 Technology Risk Bulletin discusses identity, tool restrictions, testing, traceability and resilience for generative and agentic AI. It complements existing guidelines with sound practices. E-23’s revised model-risk guideline is effective 1 May 2027; determine system applicability with the institution’s model-risk function. [R01][R02]
These references inform the design. They do not establish that the proposed architecture, or any named product, complies with every applicable requirement.
Reuse first: the minimum payment pilot
These are logical responsibilities, not a shopping list of new products. Confirm which capabilities the client already operates before estimating integration work.
| Responsibility | Reuse / verify | Minimum change | Owner |
|---|---|---|---|
| Task and context | Azure Boards, repository and API contract | Add a read-only versioned context adapter | QE platform + application lead |
| Model access | Approved model endpoint and identity | Configure a scoped model adapter, quotas and timeout handling | AI platform owner |
| Execution and authorization | Azure Pipelines, protected branches, service identities | Configure isolated runners and independent action allowlists | DevOps + service owner |
| Data and provider behavior | Current test database and vendor integration slots | Add resettable fixtures and validated WireMock scenarios; retain real-provider checks | Test-data + integration lead |
| Evidence and review | Pipeline artifacts, results and release approval | Add stable joins, a read-only summary and missing-evidence holds | QA + release owner |
Build thin adapters only where supported integration is missing. Select an existing approved product when it can provide the same interface, evidence export and operational ownership. A shared model router, Kubernetes cluster or vector store is not a universal prerequisite.